
Alternatives to Crawlkit
Explore the best alternatives and competitors to Crawlkit.
Explore 20 alternatives to Crawlkit. Compare features, pricing, and find the best fit for your needs.
ROIpad
ROIpad provides dynamic competitive positioning intelligence for SaaS. Identify high-converting messaging gaps and outmaneuver rivals with live data.
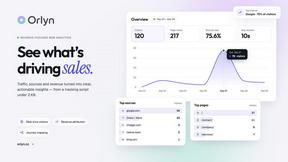
Orlyn
Privacy-first, cookieless analytics that connects website traffic to real revenue. Sub-1KB script, no cookie banners.
BillionVerify
BillionVerify is a professional email verification service built to solve one problem: bad email data costs businesses money.
GetYouTubeTranscript
Free YouTube transcripts on the web, a Chrome extension, and an API + MCP server so AI assistants can read YouTube.
layahost
Moderation, routing, intent and scoring for any text over one Jev-compatible API, hosted in the EU.
tally counter
Browser-based gamepad diagnostic tool for testing controller buttons, analog sticks, triggers, D-pad controls, and input detection.
ContextBolt SEO
Research keywords, competitors, backlinks and AI visibility inside Claude or Codex, with findings saved to your SEO dashboard.
Built2WinWeb AI SEO
AI‑ready websites, WebAgentScan SaaS, and Indexing Pack. MCP, A2A, llms.txt — hand‑coded PHP, complete ownership, flat‑fee, free quote.
SnapPChart
SnapPChart grades a trading chart screenshot A+ to F, with an entry, stop, targets, and risk/reward. Works on stocks, forex, crypto, futures.
Insta Bio
InstaBio is a free Instagram bio generator offering stylish Unicode fonts, attitude lines, and Hindi devotional bios (Radhe Krishna, Mahadev).
Postqued
Schedule and publish social content across 10 platforms with one dashboard, API, and MCP built for teams and AI agents.
AI Image Remover
AI Image Remover is a free browser tool for erasing people and objects from photos. Upload an image, brush a mask over the distraction
Wisegrid
Spreadsheet-native work management with AI formulas, dashboards, automation, reporting, and project views for growing teams.
VideoAny BR
Create AI videos from text or images, generate images and audio in one online studio.
About Crawlkit Alternatives
Crawlkit is a developer-centric platform in the web data extraction and analytics category. It provides a robust API to simplify accessing website data and screenshots by handling complex infrastructure like proxies and anti-bot systems internally. This allows technical teams to bypass operational headaches and focus on their core data workflows. Users explore alternatives for various practical reasons. Cost considerations, specific feature requirements like data point limits or export formats, and the need for a different user interface—such as a visual scraper versus an API-first tool—are common drivers. The scale of a project, from a simple one-time scrape to a massive, ongoing data pipeline, also significantly influences the choice. When evaluating options, key criteria include the platform's reliability and success rate against modern websites, its scalability and performance under load, and the total cost of ownership. Security and data handling practices are paramount, as is the quality of developer experience, including API design, documentation, and available SDKs.
FAQs about Crawlkit Alternatives
What is Crawlkit?
Crawlkit is a reliable, API-first platform engineered for developers and data teams to extract data and screenshots from any website, abstracting away the complexity of proxies and anti-bot measures.
Who is Crawlkit for?
It is built specifically for developers and data teams who need scalable, reliable web data extraction without building and maintaining their own fragile scraping infrastructure.
What are the main features of Crawlkit?
Key features include a universal crawling endpoint with JavaScript rendering, built-in anti-block infrastructure for high success rates, and support for multi-format data extraction beyond just HTML.
Why choose Crawlkit?
Crawlkit allows users to focus entirely on data analysis and application logic by providing a single, reliable API that handles the operational overhead of modern web scraping.